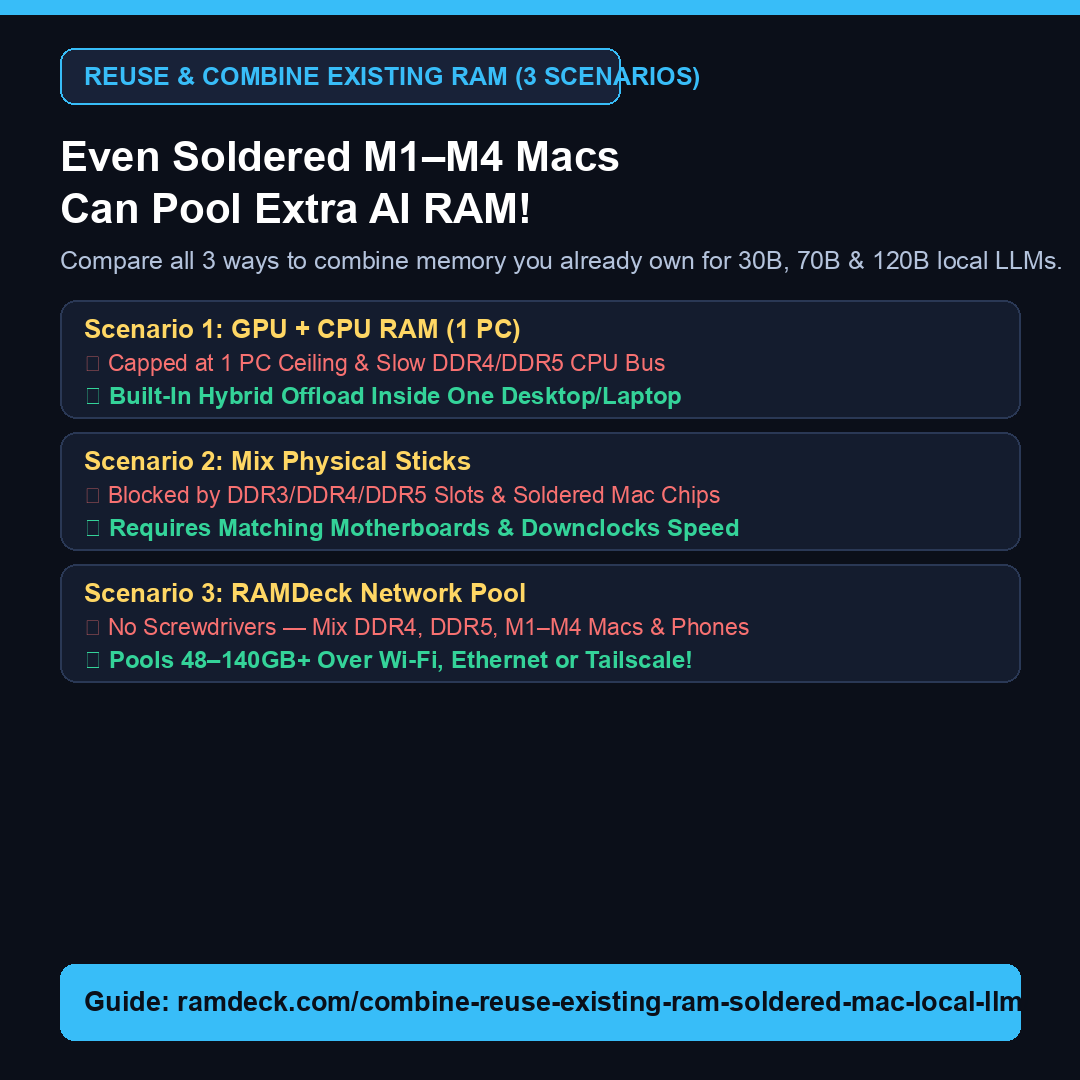
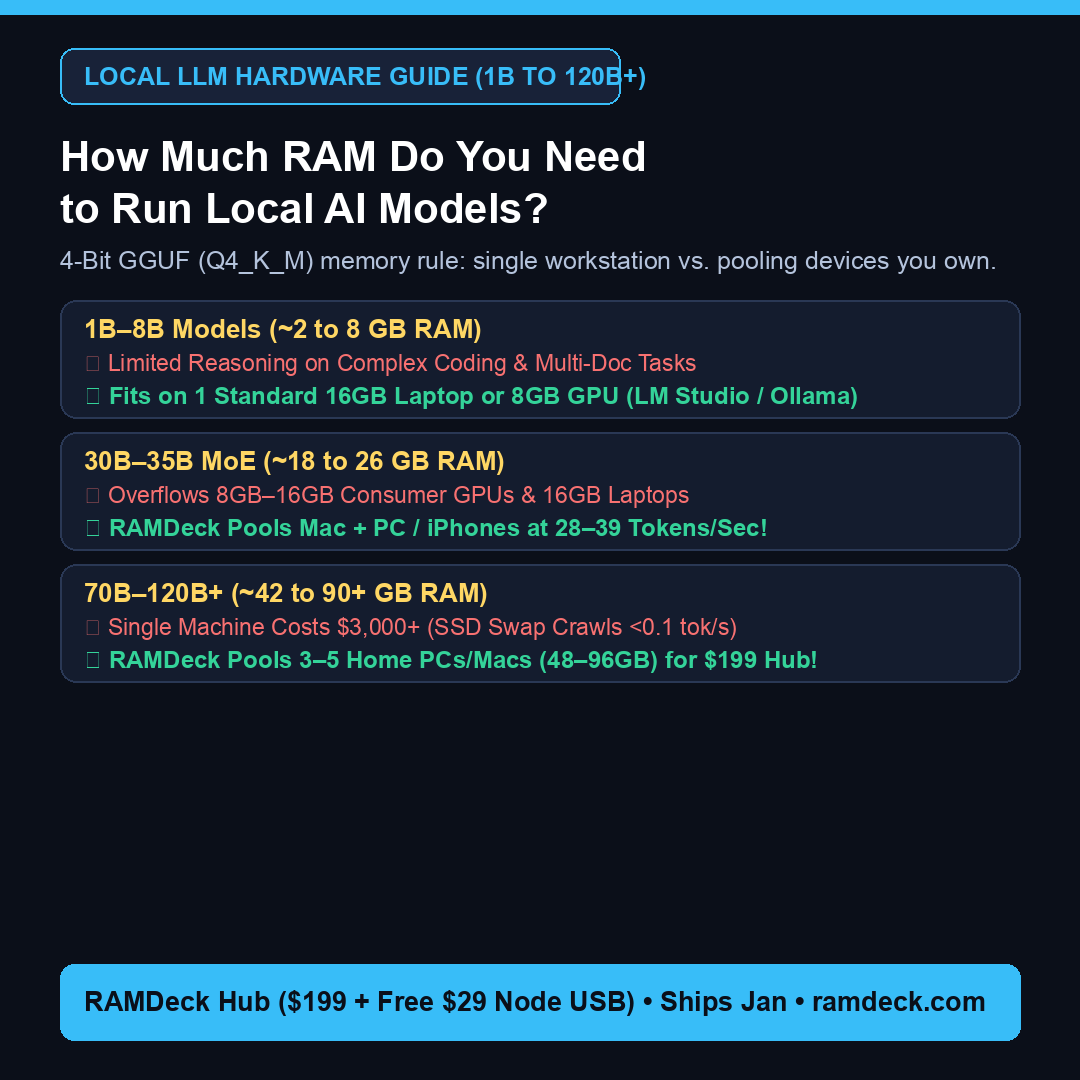
Direct Answer: Models like Qwen 2.5 Coder 32B, Qwen3-Coder 30B, and DeepSeek-R1-Distill-32B deliver near-frontier coding and reasoning, but their ~18 GB to 19.8 GB Q4_K_M weights crash any standalone 12 GB GPU or 16 GB laptop with an Out-of-Memory error. Instead of paying inflated DDR5 prices or buying a $2,000+ 24 GB–32 GB GPU, plugging the RAMDeck Hardware Hub ($199 • Includes 1 Free $29 Official Zero-Install Node USB) into your router combines two 16 GB laptops/Macs—or a 12 GB GPU desktop + 16 GB MacBook—into one 28 GB to 32 GB+ unified AI pool in 60 seconds with zero terminal coding.
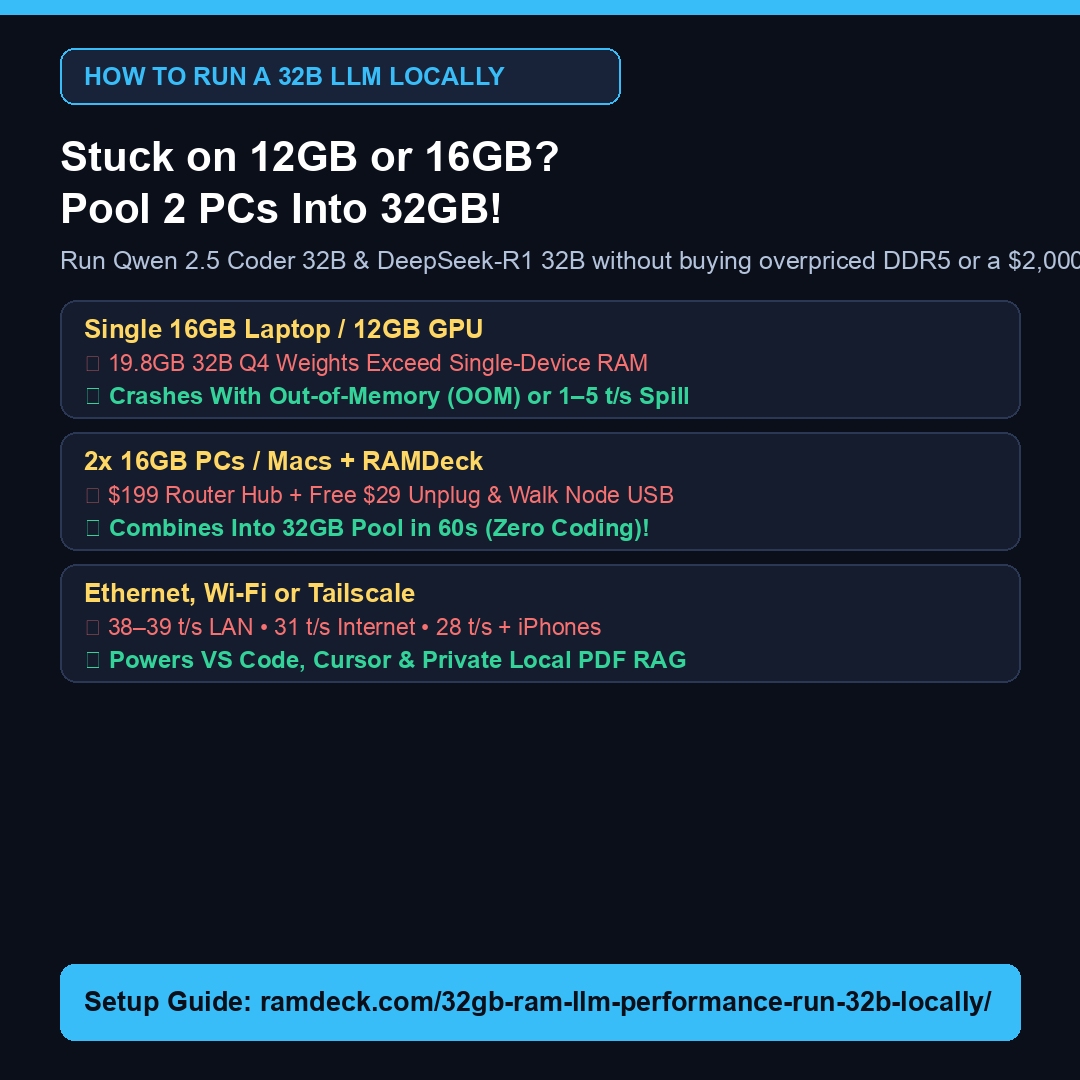
3 Verified Multi-Device Setups That Run 30B–32B Q4 Models Smoothly
- 38–39 tokens/sec (Local Ethernet): 12 GB RTX 3060 Mini PC + 16 GB M4 Mac mini (28 GB combined high-speed VRAM + Unified Memory)—6× to 10× faster than single-PC DDR4 CPU spillover.
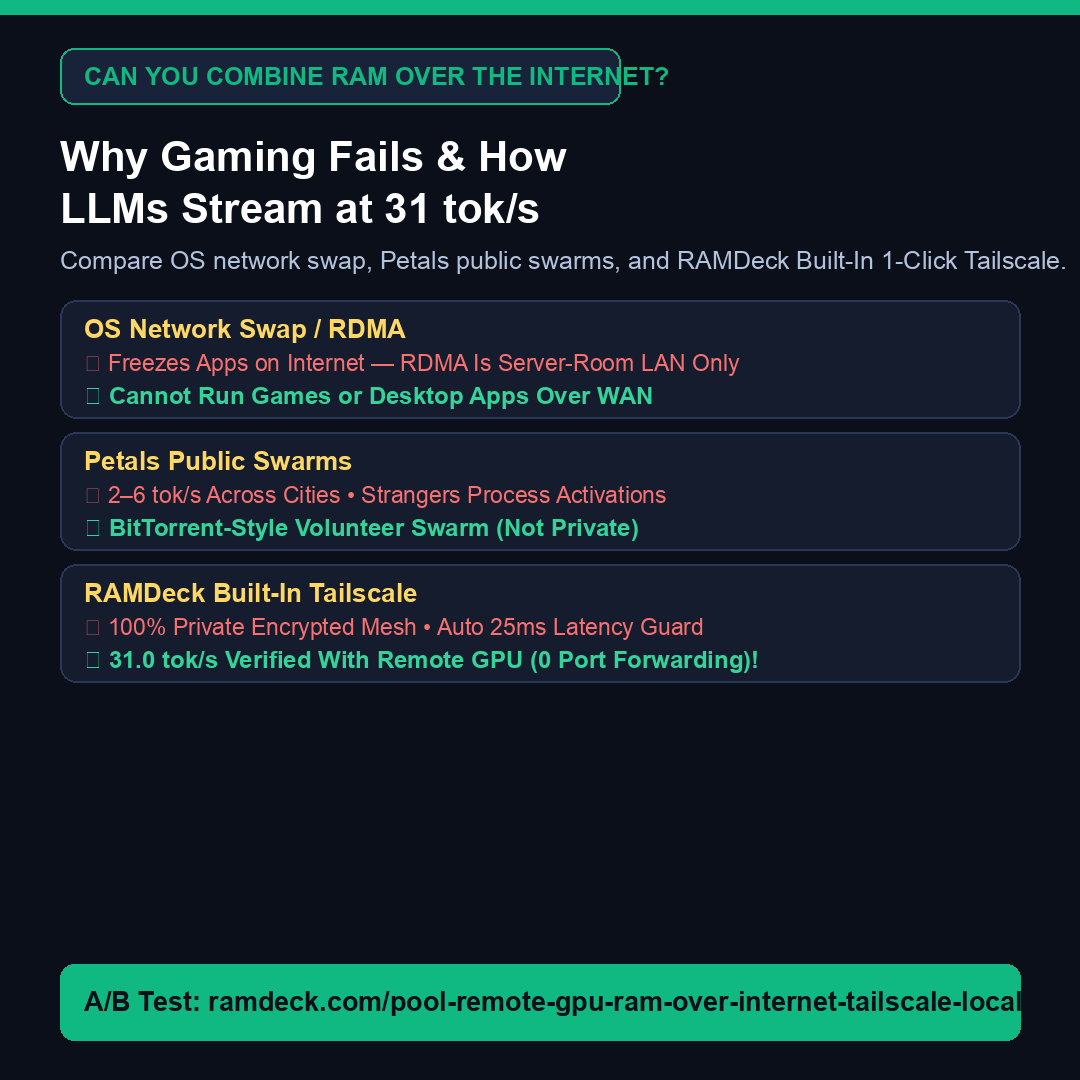
- 31.0 tokens/sec (Over the Internet via Built-In 1-Click Tailscale): Local 12 GB GPU Mini PC + remote MacBook Air miles away (~6 ms encrypted tunnel, zero port forwarding).
- 28.0 tokens/sec (Home Wi-Fi + iPhones): Soldered 16 GB M3 MacBook + two iPhones contributing unified memory via RAMDeck’s official Apple App Store app.
Read the complete step-by-step guide at How to Run a 32B LLM Locally & 32GB RAM Performance Guide and How to Run 32B, 70B & 120B Models Locally.
— The TradeMAV Team
Trademark Notice: TradeMAV™ is a trademark of TradeMAV LLC. All third-party product and model names, including Qwen, DeepSeek, Gemma, Llama, LM Studio, Ollama, VS Code, Cursor, Continue.dev, Apple, Mac, iPhone, Windows, Linux, Android, and Tailscale, are trademarks or project names of their respective owners, which are not affiliated with, sponsoring, or endorsing RAMDeck or TradeMAV LLC.
About the Author