For law firms, accounting practices, and clinical offices, public cloud AI APIs pose a substantial regulatory and ethical challenge. Under legal confidentiality standards like ABA Formal Opinion 512, client communications and sensitive records cannot be transmitted to third-party cloud models.
Yet small professional offices often cannot justify the massive capital expenditure required to install enterprise AI server racks. The practical answer lies in on-premise distributed inference.
Local LAN Coordination Without Data Egress
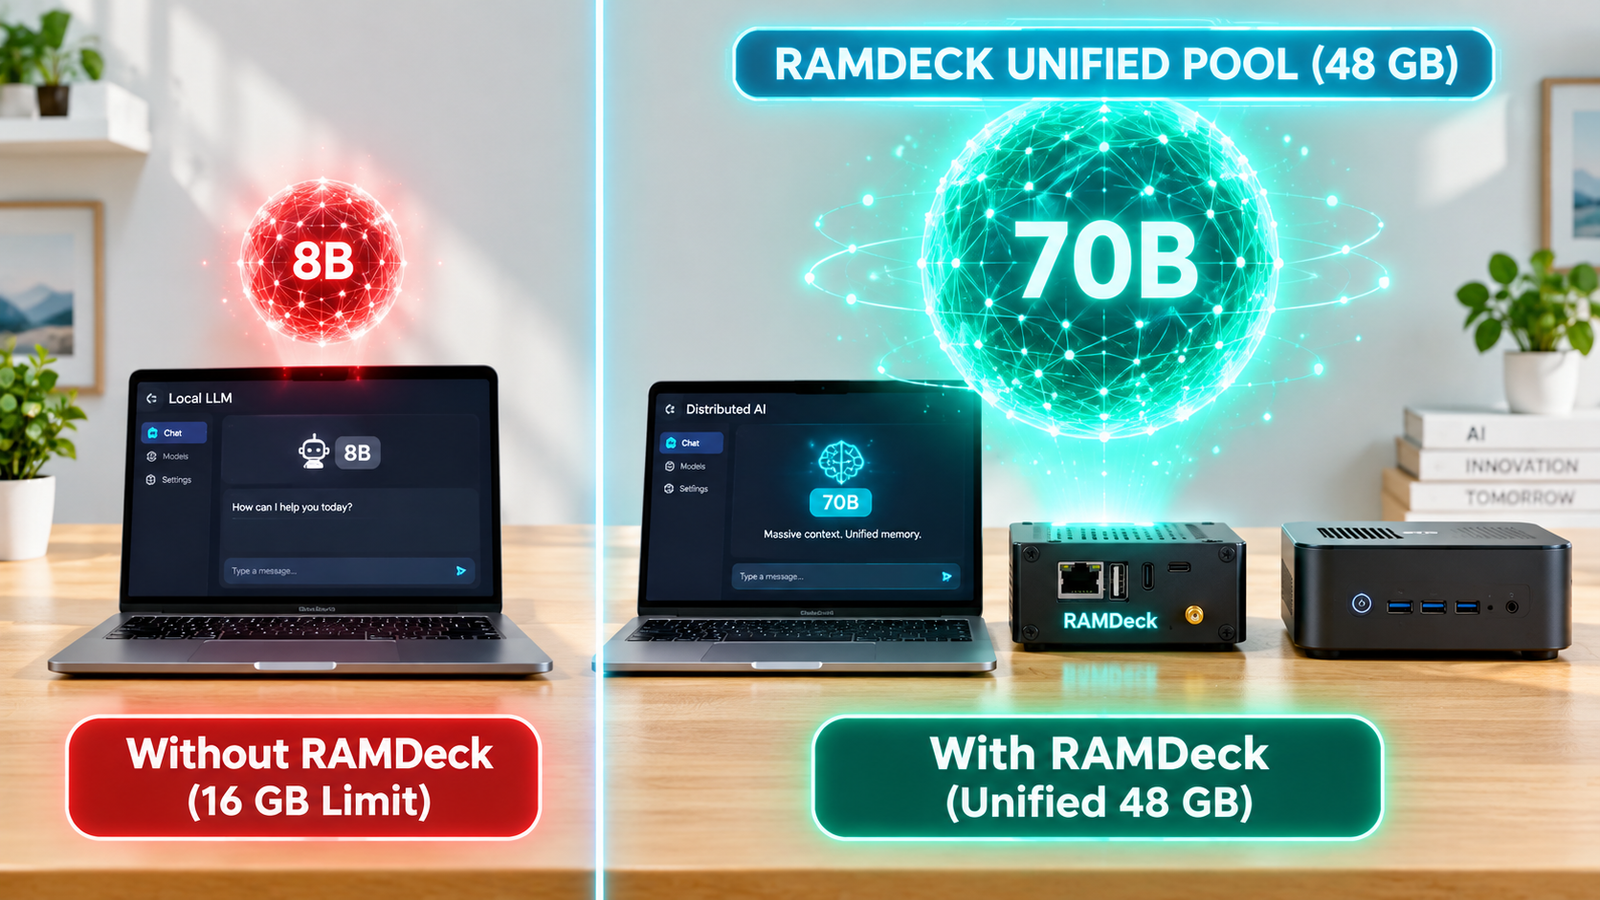
By orchestrating standard office desktops and laptops into a private local cluster, RAMDeck enables full 70B parameter models to evaluate entirely inside your office network. Model layers are partitioned sequentially across devices, and intermediate tensor activation vectors (~16 KB) transfer over standard office Gigabit switches in just 0.13 milliseconds.
Zero bytes of prompt text, customer records, or telemetry ever exit your local network. You gain state-of-the-art document drafting, analysis, and coding capabilities with 100% data sovereignty.
Explore the complete architecture guide: How to Run an LLM Across Multiple Computers Without a GPU.
To deploy turnkey plug-and-play coordination in your office, reserve the RAMDeck Hardware Hub on Indiegogo.
— The TradeMAV Team
About the Author